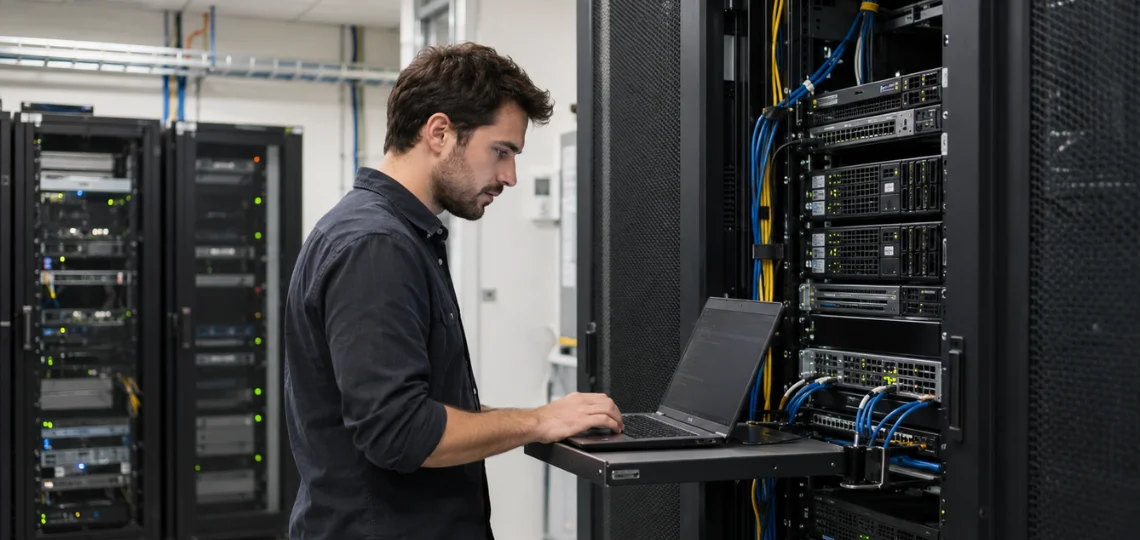
Most of what infrastructure engineers build is meant to be invisible. A deployment pipeline that works doesn't get a mention in a customer email. An auto-scaling policy that quietly absorbs a traffic spike doesn't show up in a product review. Nobody thanks the load balancer. That's the nature of the job, and it's exactly why it's one of the easiest engineering functions for a growing company to underinvest in. The cost of that gap tends to show up at the worst possible moment: during a traffic spike, a security incident, or a critical release.
What's Below the Surface
The role spans a broader set of responsibilities than it often gets credit for. Deployment and release infrastructure builds the pipelines that let a team ship code safely and frequently, without manual, error-prone steps. Scaling and capacity planning ensures systems can absorb growth and traffic spikes without a scramble or a costly emergency fix. Monitoring and observability builds the visibility a team needs to catch and diagnose problems before customers do. Security and access management at the infrastructure layer is an often-overlooked responsibility that becomes critical the moment a security review or audit happens. Cost management matters because infrastructure spend can grow unnoticed until someone is specifically responsible for watching it.
Why It Stays Below the Surface
Three dynamics keep this work invisible until it isn't. Unlike a new feature, strong infrastructure work doesn't produce a visible, demoable outcome, making it easy to deprioritize in favor of feature work with obvious business impact. The cost of underinvestment is delayed because problems from weak infrastructure practices often don't surface until the system is under real load, well after the decision to underinvest was made. It is also hard to hire reactively. By the time an outage or scaling failure makes the need obvious, a company is trying to hire under pressure, which rarely produces the best outcome.
Signs the Surface Is About to Break
| Signal | What It Usually Means |
| Deployments are manual or error-prone | CI/CD investment hasn't kept pace with team growth |
| Outages happen during predictable traffic spikes | Scaling and capacity planning need attention |
| The team can't answer "why is this slow" quickly | Observability and monitoring are underdeveloped |
| Infrastructure costs are rising without a clear owner | No one is specifically responsible for cost management |
| Security review surfaces infrastructure-level gaps | Access management and security practices weren't built in early |
Investing Before the Break, Not After
The strongest engineering organizations proactively invest in infrastructure capabilities before an outage or scaling failure forces the issue. For companies that can't yet justify a full-time infrastructure team, staff augmentation offers a practical way to bring in experienced engineers to build the foundational practices, deployment pipelines, monitoring, and scaling policies that pay off well before growth would otherwise force a painful, reactive fix. This connects to the practices described for DevOps at fast-growing SaaS companies, where the same pattern of underinvestment recurs, and to the reliability discipline covered in site reliability engineering for AI systems.
AssureSoft's Standard for Infrastructure Engineering
We help companies build infrastructure capability before it becomes an emergency by bringing in experienced engineers who treat deployment, scaling, monitoring, and security as foundational work rather than an afterthought. Our engineers bring the same ownership and consistency to infrastructure work that we apply across every layer of a client's engineering organization.
AI Productivity. Human Standards.
Ready to invest in infrastructure before it becomes a crisis? Let's talk before it does.